On-premise AI server
for Indian enterprises
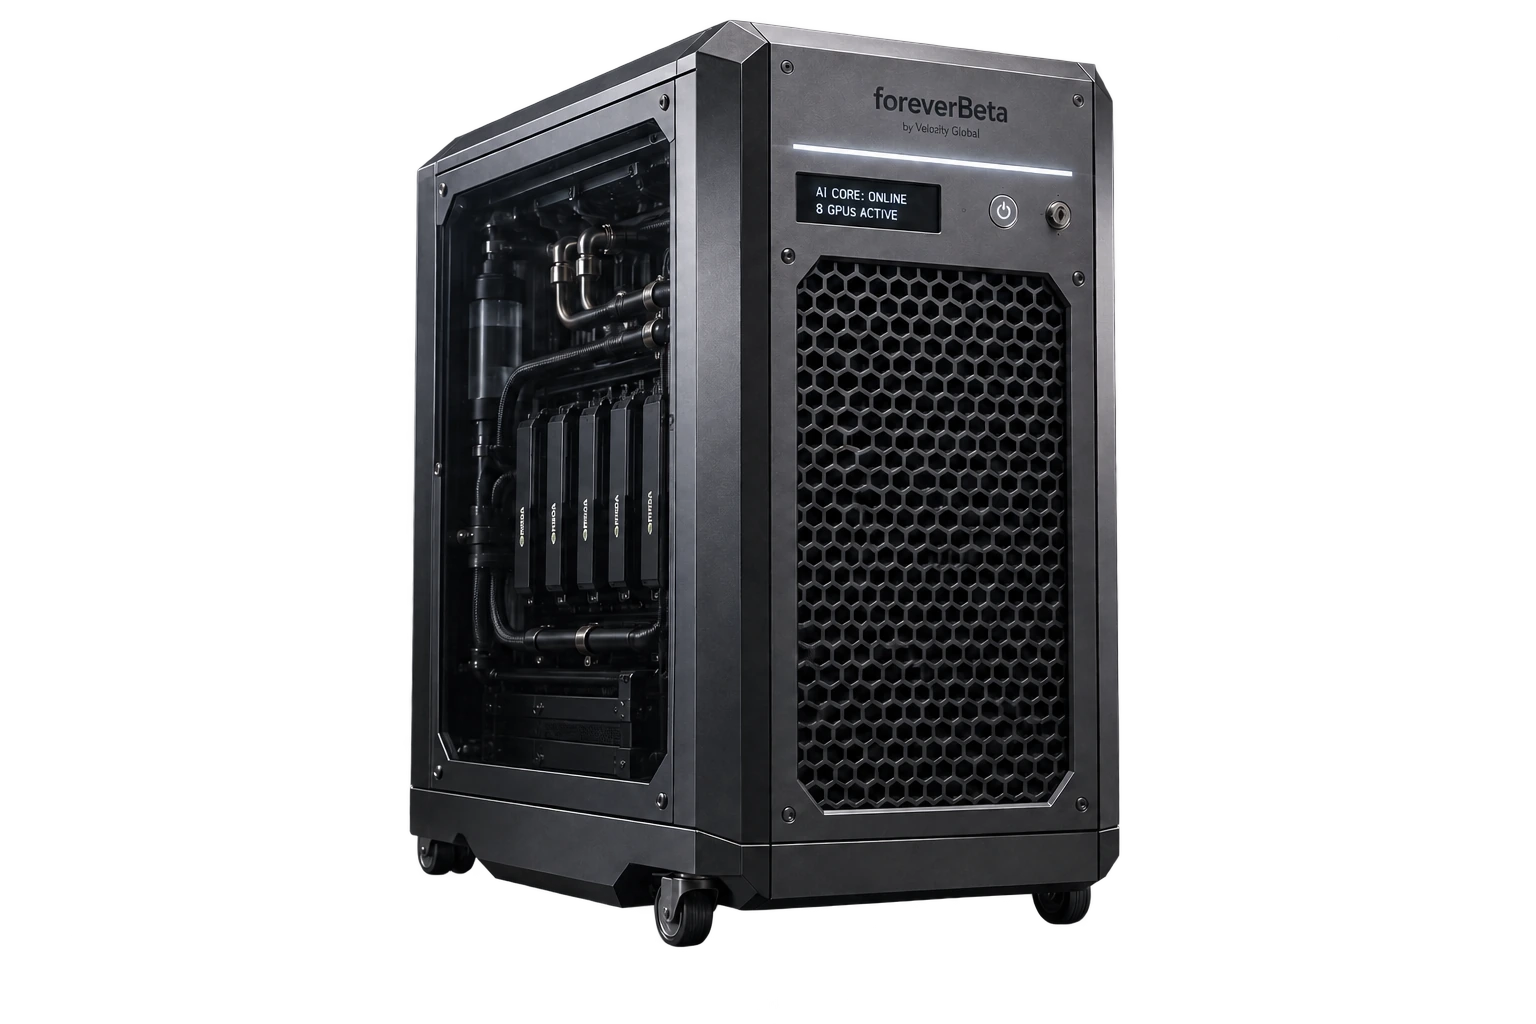
A GPU server rack with pre-loaded large language models and vision AI, served via vLLM and TGI. Run AI chatbots, document processing, code generation, and custom workflows entirely within your premises. Zero data leaves your network.
What you are dealing with today.
Sensitive data cannot leave the premises
Banks, insurers, pharma companies, and government agencies face strict data sovereignty requirements. Sending customer data, financial records, or patient information to cloud AI APIs is a compliance risk.
Cloud AI API costs scale unpredictably
When AI workflows process thousands of documents or queries daily, per-token cloud API costs become significant. A single department can rack up 3-5 lakhs per month in API fees at scale.
Cloud API latency and rate limits slow down workflows
Cloud AI APIs introduce network latency and impose rate limits. Batch processing 10,000 documents through a cloud API can take hours. On-premise inference eliminates both bottlenecks.
From setup to results.
Install the server in your existing data centre or server room
The server ships as a standard 4U rack-mount unit. It requires a 30-amp power connection and standard rack cooling. Installation and network configuration take 1-2 days.
Server Status
Operational| Component | Status | Utilisation | Temp |
|---|---|---|---|
| GPU 0 | Active | 68% | 62°C |
| GPU 1 | Active | 54% | 58°C |
| GPU 2 | Active | 72% | 64°C |
| GPU 3 | Idle | 2% | 38°C |
Pre-loaded models are ready to use
The server comes with popular open-source LLMs (Llama 3, Mistral, Gemma) and vision models pre-loaded and optimised. Models are served via vLLM or TGI with an OpenAI-compatible API endpoint.
Pre-loaded Models
Load Model| Model | Size | Type | Status | Requests/min |
|---|---|---|---|---|
| Llama 3.1 70B | 40GB | LLM | Running | 240 |
| Mistral 7B | 4GB | LLM | Running | 800 |
| Whisper Large v3 | 3GB | Speech | Running | 120 |
| SDXL Turbo | 7GB | Image | Standby | — |
Connect your applications to the local AI API
Your developers point existing applications to the local API endpoint instead of OpenAI or Azure. The API is drop-in compatible. Existing code works with a one-line URL change.
API Endpoints
All healthyGET /v1/models 200 OK · 12ms
POST /v1/audio/transcriptions 200 OK · 2.1s
Run AI workflows with full data sovereignty
Document summarisation, contract review, customer support chatbots, code generation, and custom workflows all run locally. Monitor usage, performance, and model accuracy from the admin dashboard.
Privacy Dashboard
100% on-premWhat you get.
Enterprise-grade GPU hardware
NVIDIA A100 or L40S GPUs with 48-80 GB VRAM. Supports models up to 70B parameters. Dual-GPU configurations available for larger models or higher throughput.
GPU Cluster
vLLM and TGI model serving
Models are served via vLLM or Hugging Face TGI for optimised throughput and latency. Continuous batching, quantisation, and speculative decoding are configured out of the box.
Inference Engine
OpenAI-compatible API
The local API endpoint is compatible with OpenAI client libraries. Switch from cloud to on-premise by changing one URL. Supports chat completions, embeddings, and function calling.
API Compatibility
client = OpenAI(base_url="http://your-server:8000/v1")
# Drop-in replacement — same SDK, local inference
Multi-model hosting
Run multiple models simultaneously for different use cases. A code assistant, a document summariser, and a customer chatbot can each use a different model on the same server.
Model Router
| App | Model | Priority |
|---|---|---|
| Customer Support | Llama 70B | High |
| Doc Summary | Mistral 7B | Medium |
| Voice Agent | Whisper L | High |
Complete data sovereignty
No data leaves your network. No telemetry. No external API calls. Suitable for RBI-regulated banking data, HIPAA-adjacent healthcare data, and confidential legal documents.
Compliance
Usage monitoring and model management
Track tokens processed, latency percentiles, and model accuracy. Swap models, adjust quantisation levels, and manage API keys from the admin interface.
Resource Usage
Watch a quick demo.
On-Prem AI Server in 60 seconds.
What it looks like in practice.
Mid-size private bank, Mumbai
The bank needed to deploy AI for loan document summarisation, customer query resolution, internal knowledge search, and compliance report drafting. RBI data localisation guidelines prohibited sending customer financial data to external cloud AI APIs. Cloud GPU rental costs were projected at over 4 lakhs per month.
After deploying the On-Prem AI Server, the bank launched four AI workflows within 60 days. Loan document processing time dropped by 55%. Zero customer data leaves the bank premises. Monthly AI infrastructure cost is a fraction of the projected cloud spend.
"We evaluated three cloud AI providers but none could guarantee that our customer data would stay within India, let alone within our own network. The on-prem server gave us full control. Our compliance team signed off on day one, and our developers had the API running within a week."Vikram R., CTO, Private Sector Bank
Works with your existing tools.
Enterprise-ready from day one.
Deployment
- 4U rack-mount server
- 30-amp single-phase power requirement
- Standard data centre cooling sufficient
- Gigabit ethernet connectivity
- Remote management via IPMI/BMC
Security and data
- All inference runs on-premise with zero external calls
- No telemetry or usage data sent to vendors
- Encrypted storage for model weights and data
- Role-based API key management
- Compatible with your existing network security policies
Clear pricing. No surprises.
Pricing depends on your team size, deployment, and support needs.
Plus ₹35,000/month for support, updates, and model management. GST extra.
INCLUDES
- GPU server hardware (base configuration)
- Pre-loaded and optimised LLM and vision models
- vLLM/TGI serving stack configured
- OpenAI-compatible API endpoint
- Installation and network configuration
- First-year hardware warranty and support
Built for specific needs.
Good fit
- Banks and NBFCs needing AI without data leaving premises
- Pharma and healthcare companies with patient data sensitivity
- Government departments and PSUs with data localisation mandates
- Legal firms processing confidential contracts and documents
- Any enterprise spending over 2 lakhs per month on cloud AI APIs
Not designed for
- Startups and small teams with occasional AI usage (cloud APIs are more economical)
- Companies without a server room or data centre facility
- Teams needing only pre-built SaaS AI tools (no custom development planned)
- Businesses comfortable with cloud AI and without data sovereignty concerns
How much does the On-Prem AI Server cost?+
Configurations start at ₹5,99,999. Dual-GPU and high-memory configurations are available at higher price points. The monthly support and model management subscription is ₹35,000. GST is additional.
What models come pre-loaded?+
The server ships with Llama 3 (8B and 70B), Mistral 7B, and Gemma models pre-loaded and optimised. Additional open-source models can be loaded on request. Proprietary models are not included.
Can our developers use it like OpenAI?+
Yes. The API endpoint is compatible with the OpenAI Python SDK. Existing code using openai.ChatCompletion works by changing the base URL to your local server. No other code changes needed.
What GPU options are available?+
The base configuration includes one NVIDIA L40S (48 GB VRAM). Upgraded configurations with NVIDIA A100 (80 GB VRAM) or dual-GPU setups are available for larger models and higher throughput.
Do we need a dedicated server room?+
The server needs a standard 19-inch rack, 30-amp power, and adequate cooling. It runs in existing server rooms or colocation facilities. It is not designed for office environments without proper ventilation.
How is it different from renting cloud GPU instances?+
You own the hardware outright. There are no hourly GPU rental fees, no per-token charges, and no data leaving your premises. For sustained AI workloads, on-premise is typically 40-60% cheaper than cloud GPU over 18 months.
Can you help us fine-tune models on our data?+
Yes. We offer model fine-tuning as a professional service. Your data stays on-premise throughout the process. Fine-tuned models are deployed directly to your server.
What happens when new models are released?+
The monthly support subscription includes assistance with loading and optimising new open-source models as they are released. Model updates are tested and configured by our team.
Related guides.
On-premise vs cloud AI
When to keep AI processing on-site instead of the cloud.
Read the guideEnterprise knowledge that stays useful
Building internal knowledge systems that teams actually rely on.
Read the guideFrom AI prototype to production
What changes when you move from demo to daily use.
Read the guideLooking for pricing, comparisons, and use cases? See our detailed guide: On-Premise AI Server India
On-Prem AI Server.
Let's set it up.
Book a 20-minute demo, get a quote, or just ask a question.
Our team in Chennai responds within one working day.